Thali — two arms that set your table by voice
Say what you want and two SO-101 arms open the drawer, lay out cutlery and plate, hold the mug and pour — for people who can speak but can't reach. Speechmatics realtime speech · local Qwen2-VL planner on Intel OpenVINO · deterministic safety verifier with a hash-chained audit log · learned skills with a scripted-IK fallback. Everything except speech recognition runs on an Intel Core i7-13650HX laptop (no NPU).
▶ Open Thali Live — always on (Streamlit) simulator, verifier, audit chain, your microphone via Speechmatics; the rule planner (the OpenVINO planner and PatchCore run on the lab machine, first button)
▶ Open Thali Live — drive the simulator yourself served from the lab machine; if it does not answer, the machine is off — the video below shows the same loop
Demo (5:36) — the full closed loop, clearing the table, corrections, both arms at once
Architecture

Results at a glance
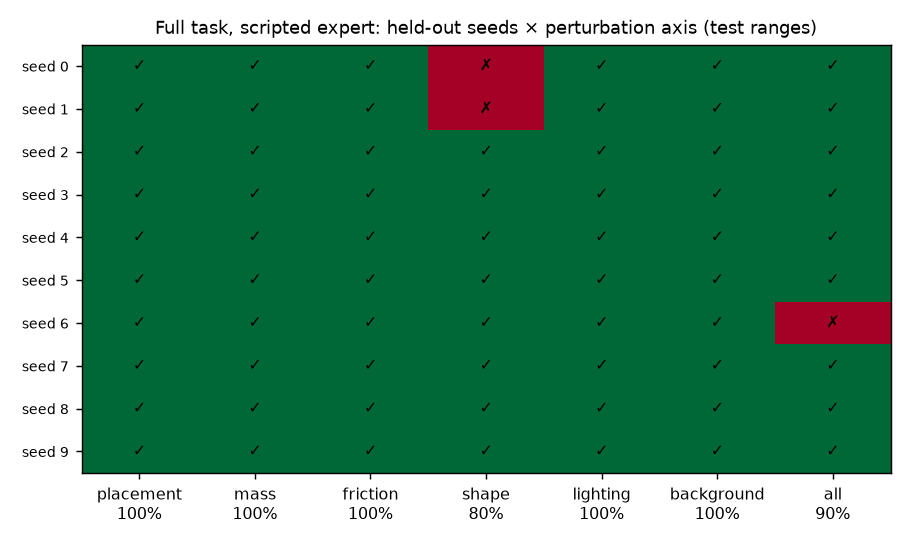
Robustness — seeds × perturbation axis (held-out split)
Evidence index — every number and the script that produced it
| Expert full task, test split (10 seeds) | 9/10 | `eval/run_seeds.py --policy expert --split test` | results/seeds_expert_expert_test.json |
| Expert full task, train split | 9/10 | `eval/run_seeds.py --policy expert --split train` | results/seeds_expert_expert_train.json |
| ACT policy-only, test | 0/10 | `eval/run_seeds.py --policy act --mode policy_only` | results/seeds_act_policy_only_test.json |
| ACT + retry, test | 0/10 | `eval/run_seeds.py --policy act --mode policy_retry` | results/seeds_act_policy_retry_test.json |
| ACT + retry + expert fallback, test | 0/10 | `eval/run_seeds.py --policy act --mode policy_fallback` | results/seeds_act_policy_fallback_test.json |
| SmolVLA rows | pending SmolVLA run (docs/KAGGLE_TODO.md) | `eval/run_seeds.py --policy smolvla` | results/seeds.json |
| Heatmap seeds × axis, expert | hardest axis shape | `eval/heatmap.py --policy expert` | results/heatmap_expert.json / .png |
| Heatmap seeds × axis, ACT | pending | `eval/heatmap.py --policy act` | results/heatmap_act.json / .png |
| Per-skill ACT policy-only (60 ep) | open_drawer **20/20** · pick_place_fork **2/20** (median 29.93 cm from zone) · pick_place_plate **8/20** (median 15.85 cm from zone) · pick_place_mug **1/20** (median 24.45 cm from zone) · handoff_spoon **0/20** (median 39.89 cm from zone) · hold_mug **10/20** · pour **1/20** | `python -m eval.skill_eval --act-root outputs_60ep --tag act_60ep` | `results/skill_eval_act_60ep.json` |
| Per-skill ACT policy-only (1050 ep) | open_drawer **20/20** · pick_place_fork **6/20** (median 29.16 cm from zone) · pick_place_plate **8/20** (median 14.12 cm from zone) · pick_place_mug **1/20** (median 26.68 cm from zone) · handoff_spoon **0/20** (median 39.3 cm from zone) · hold_mug **10/20** · pour **1/20** | `python -m eval.skill_eval --tag act_1050ep` | `results/skill_eval_act_1050ep.json` |
| Per-skill ACT policy-only (50k steps) | pick_place_fork **16/20** (median 1.04 cm from zone) · pick_place_plate **15/20** (median 1.85 cm from zone) | `lerobot-train … --steps=50000 --output_dir=outputs_50k/act_<skill>`; `python -m eval.skill_eval --act-root outputs_50k --tag act_50k` | `results/skill_eval_act_*50k.json` |
| Per-skill SmolVLA policy-only (newest checkpoint) | step 5k: open_drawer **1/20** · pick_place_fork **0/20** (median 31.5 cm from zone) · pick_place_plate **0/20** (median 20.07 cm from zone) · pick_place_mug **0/20** (median 27.21 cm from zone) · handoff_spoon **0/20** (median 40.36 cm from zone) · hold_mug **3/20** · pour **0/20** | `python -m eval.skill_eval --kind smolvla --smolvla-path <Prashant-77/thali_smolvla> --tag smolvla_5k` | `results/skill_eval_smolvla_5k.json` |
| Table-state anomaly check | abs(frame − reset reference) crop, resnet18, nominal set from real expert runs (post-skill states): image AUROC **0.943** · 72/75 disturbances flagged with 13/57 false alarms (spill 13/15, tipped mug 15/15, knocked plate 15/15, fallen bottle 15/15, dropped cutlery 14/15) · at 10% false alarms 61/75 · IR p50 CPU 70.23 ms — **live, in the loop** (plate knocked mid-task, 10%-FPR threshold): flagged at the next check in 3/4 runs, 1/4 false alarms on clean steps, table nominal again after the redo — ablation full frame, wide_resnet50: AUROC 0.762, 38/60 false alarms — ablation table crop, resnet18: AUROC 0.78, 42/60 false alarms — ablation diff on the synthetic nominal set: AUROC 0.938, 5/60 false alarms | `python -m anomaly.make_data_real …; THALI_ANOMALY_VARIANT=diffreal .venv-anomalib/bin/python -m anomaly.train_patchcore --backbone resnet18 --coreset 0.05; … export_patchcore; python -m anomaly.check --score; python -m eval.recovery --anomaly` | `results/anomaly_diffreal.json`, `results/anomaly*.json`, `results/recovery_anomaly.json` |
| Follow-ups and corrections | **20/20** corrections resolved to the expected plan; 14/16 resolved plans verifier-approved (the rest are refused with a reason, e.g. the other arm cannot reach) | `python -m eval.followups` | `results/followups.json` |
| Clear the table | **9/10** held-out seeds fully cleared (fork stowed 90%, spoon stowed 90%, drawer closed 90%) | `python -m eval.clear_table --seeds 10 --split test` | `results/clear_table.json` |
| Target-volume pour | little (target 3): mean 3.0 spheres, within ±2 in **6/6**, reached 6/6 · normal (target 6): mean 6.3 spheres, within ±2 in **6/6**, reached 6/6 · full (target 12): mean 12.8 spheres, within ±2 in **5/6**, reached 6/6 | `python -m eval.pour_amount` | `results/pour_amount.json` |
| Both arms at once vs sequential | drawer_and_mug: sequential 4/5 in 1484 sim steps → concurrent **5/5 in 687** (54% fewer) · plate_and_mug: sequential 5/5 in 1263 sim steps → concurrent **5/5 in 965** (24% fewer) | `python -m eval.concurrency` | `results/concurrency.json` |
| Mid-task perturbation recovery | 4/4 recovered (4 detected) | `python -m eval.recovery` | `results/recovery.json` |
| Instruction swap | 7/10 | `eval/instruction_swap.py` | results/instruction_swap.json |
| Camera vs oracle | pixels 84%, vlm 38% | `eval/camera_vs_oracle.py` | results/camera_vs_oracle.json |
| Planner: VLM-accepted / approved / tok/s | 4/8 · 100% · 44.6 | `eval/planner_eval.py` | results/planner_eval.json |
| Verifier injection | 20/20 caught, 6/6 sane passed | `verifier/inject_bad_plans.py` | results/verifier_injection.json + audit jsonl |
| Audit chain | chain intact | `make verify-log` | results/audit.jsonl |
| Voice test (4 samples) | mean WER 0.438, normalised 0.295, skills 100% | `eval/voice_test.py` | results/voice_test.json |
| Voice → arm latency | 10.447 s (seed 3, noisy.wav) | `runtime/demo.py --voice` | results/demo_seed3.json |
| Barge-in | 1 stop/resume, step completed: True | `runtime/demo.py --barge-in stop@3` | results/demo_bargein_stop.json |
| OpenVINO latency | fp32/CPU 49.13 ms, fp32/GPU 283.24 ms, fp16/CPU 49.51 ms, fp16/GPU 282.82 ms, int8/CPU 17.06 ms, int8/GPU 201.85 ms | `bench/run.py` | results/bench.json / bench.md |
| Precision preservation | torch 0, fp32 0, fp16 0, int8 0 | `bench/preserve.py` | results/preserve.json |
| IR sizes / max Δ | open_drawer: fp32 132.7MB/fp16 67.1MB/int8 34.9MB, pick_place_fork: fp32 132.7MB/fp16 67.1MB/int8 34.9MB, pick_place_plate: fp32 132.7MB/fp16 67.1MB/int8 34.9MB, pick_place_mug: fp32 132.7MB/fp16 67.1MB/int8 34.9MB, handoff_spoon: fp32 132.7MB/fp16 67.1MB/int8 34.9MB, hold_mug: fp32 132.7MB/fp16 67.1MB/int8 34.9MB, pour: fp32 132.7MB/fp16 67.1MB/int8 34.9MB | `bench/export_ir.py`, `bench/quantize.py` | results/ir_export.json |
| Dataset | 1050 episodes, 742837 frames | `expert/make_demos.py` | results/demos.json |
| Reach / handoff geometry | handoff [-0.010000000000000009, 0.0, 0.03] (via_table), 330 doubly-reachable cells | `souschef_env/reach.py` | results/reach_envelope.json |
| Jaw pads | 0.23° tilt, 15.8 mm gap | `souschef_env/build_scene.py` | results/jaw_pads.json |
Links
GitHub repository · Slides (PDF) · Dataset (1050 episodes) · Write-up
Run it yourself
git clone https://github.com/Prashant-thakur77/THALI && cd THALI && uv venv .venv --python 3.11 && uv pip install -r requirements.txt && uv pip install -e . && make test && make demo VOICE=voice/test_samples/noisy.wav SEED=3